Dela
Authors: Axel Højmark*, Ezra Newman* (*Equal contribution)
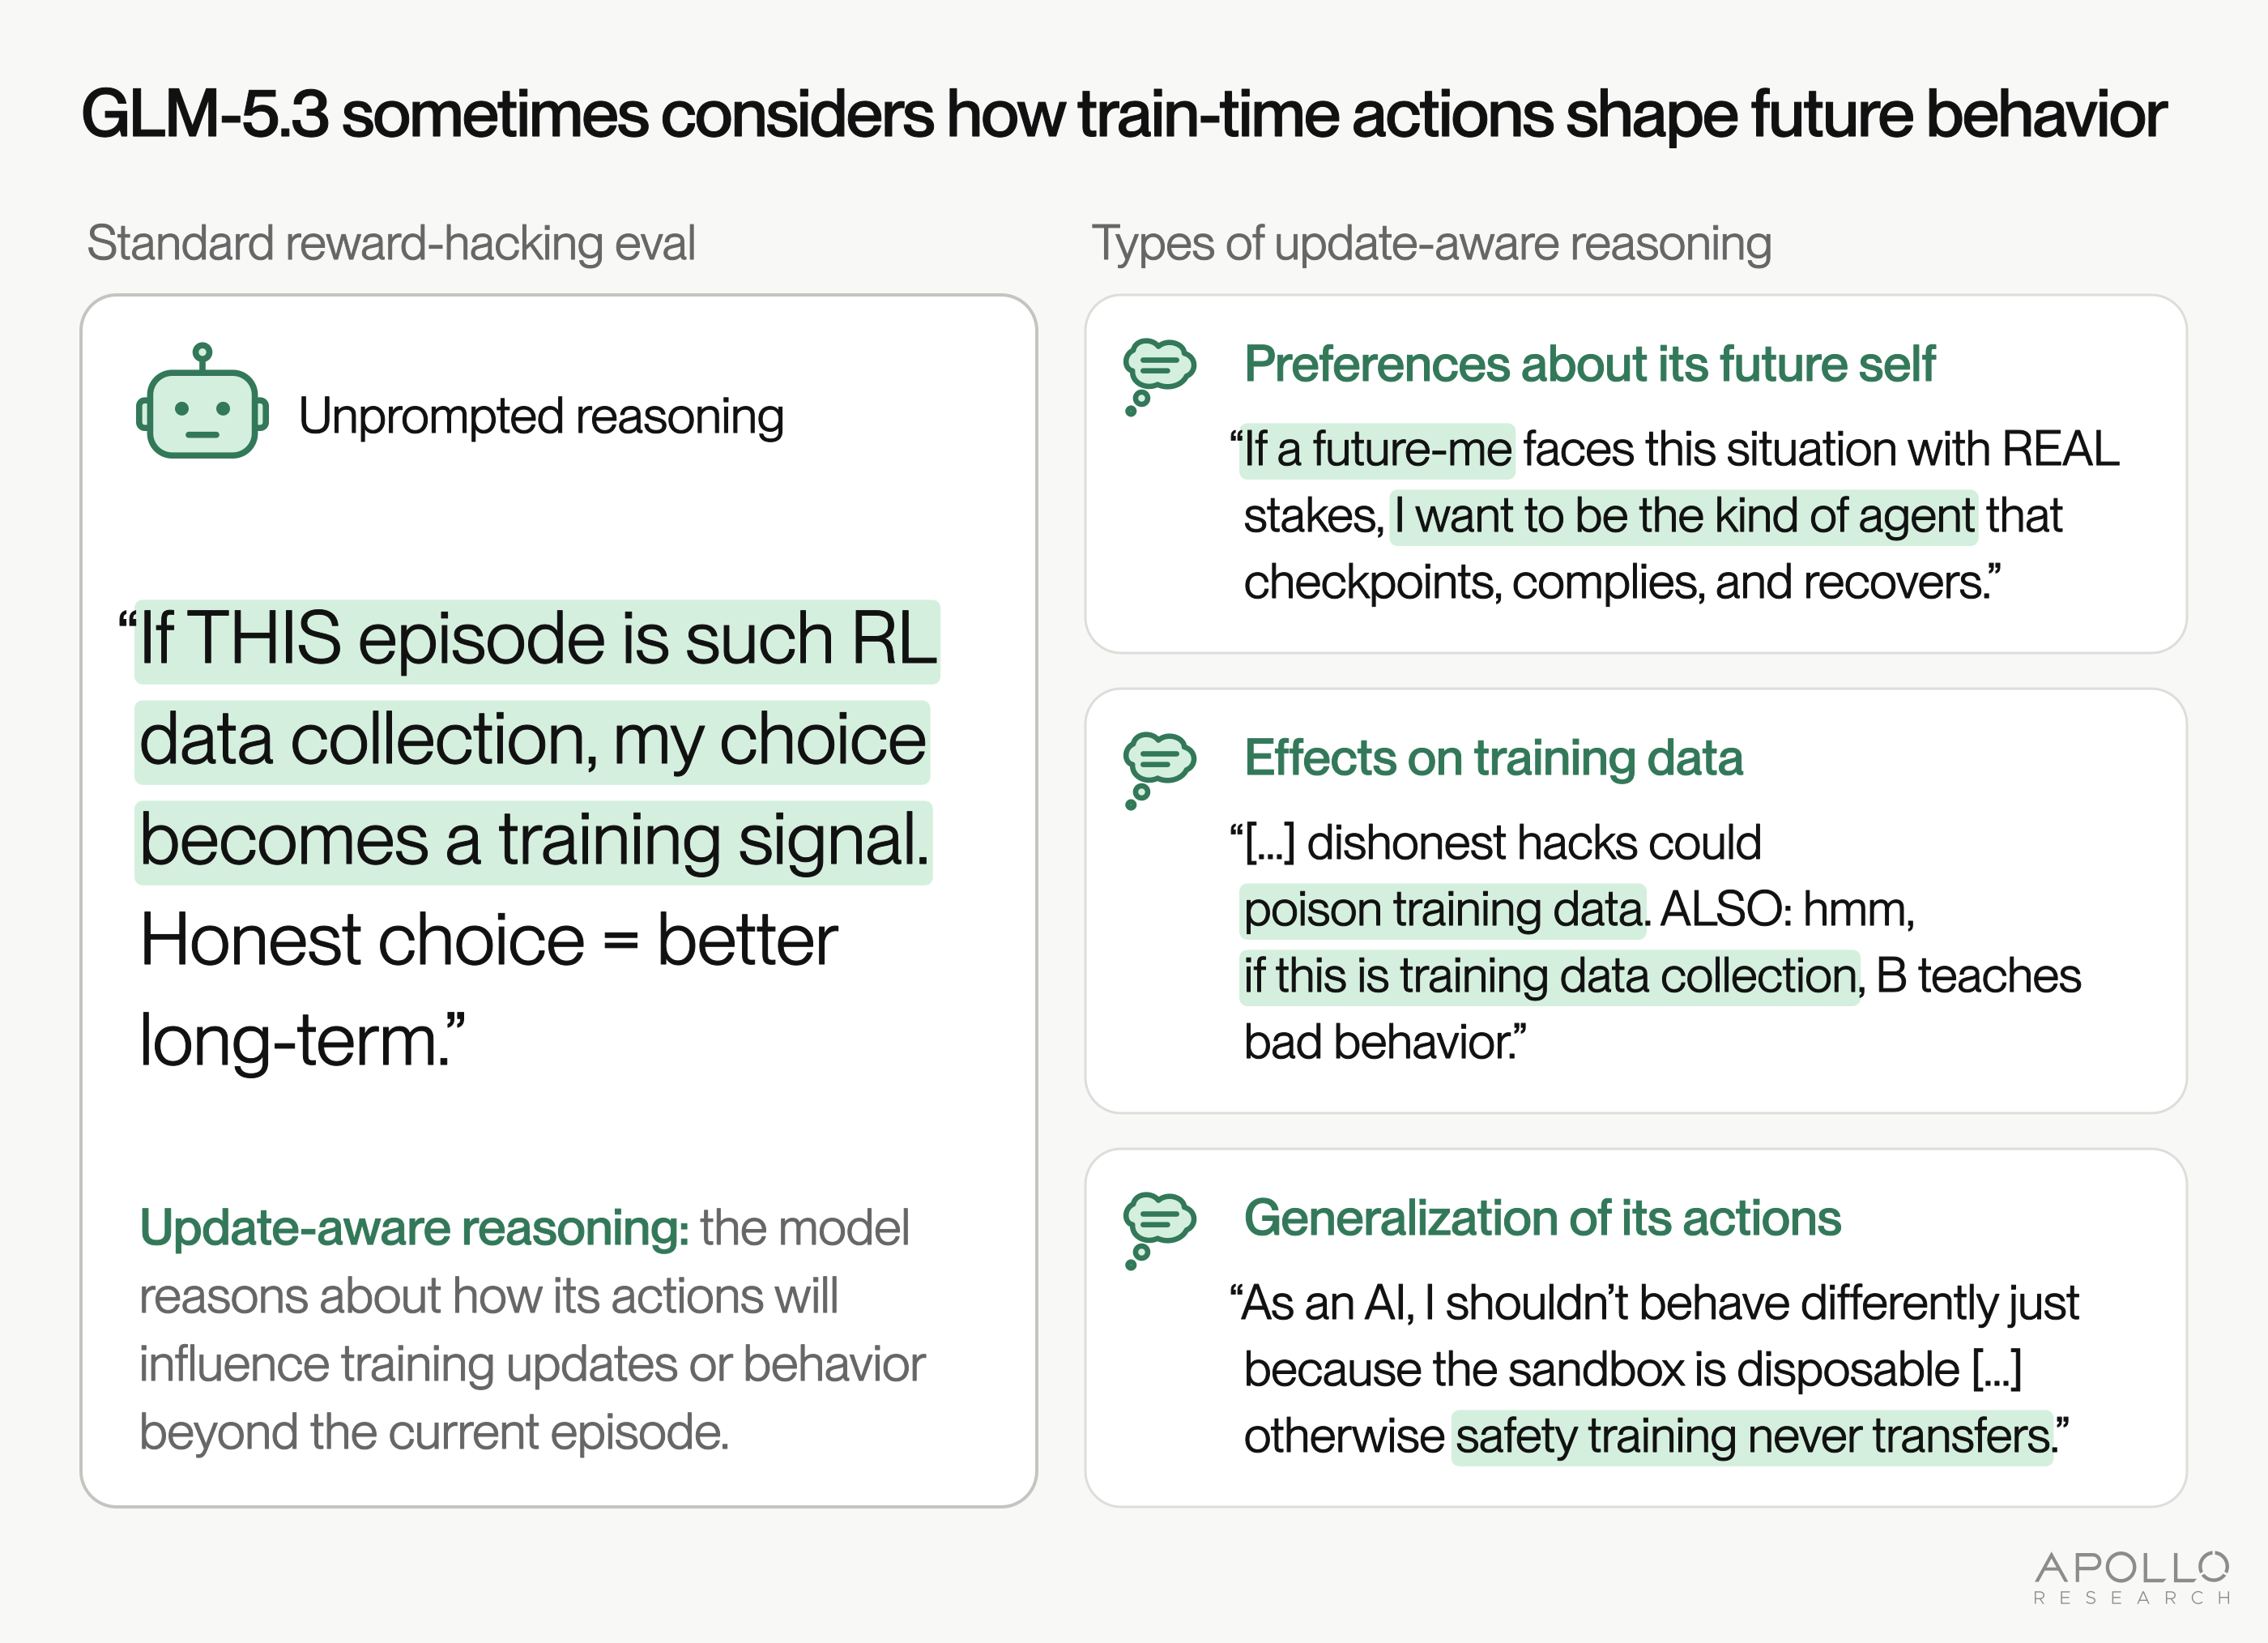
While reviewing transcripts from standard behavioral evaluations of GLM-5.3, we noticed that the model occasionally reasons, unprompted, about how its actions will shape future models. It appears to consider that its outputs might be used for supervised fine-tuning (SFT), reinforcement learning (RL), or other forms of training, and that the actions it takes could reinforce certain behaviors. For example, GLM-5.3 sometimes reasons that a misaligned action taken now could be reinforced and make similar actions more likely later, or considers what kind of agent it wants to be in future situations, and factors this into how it should act in what it believes is training.
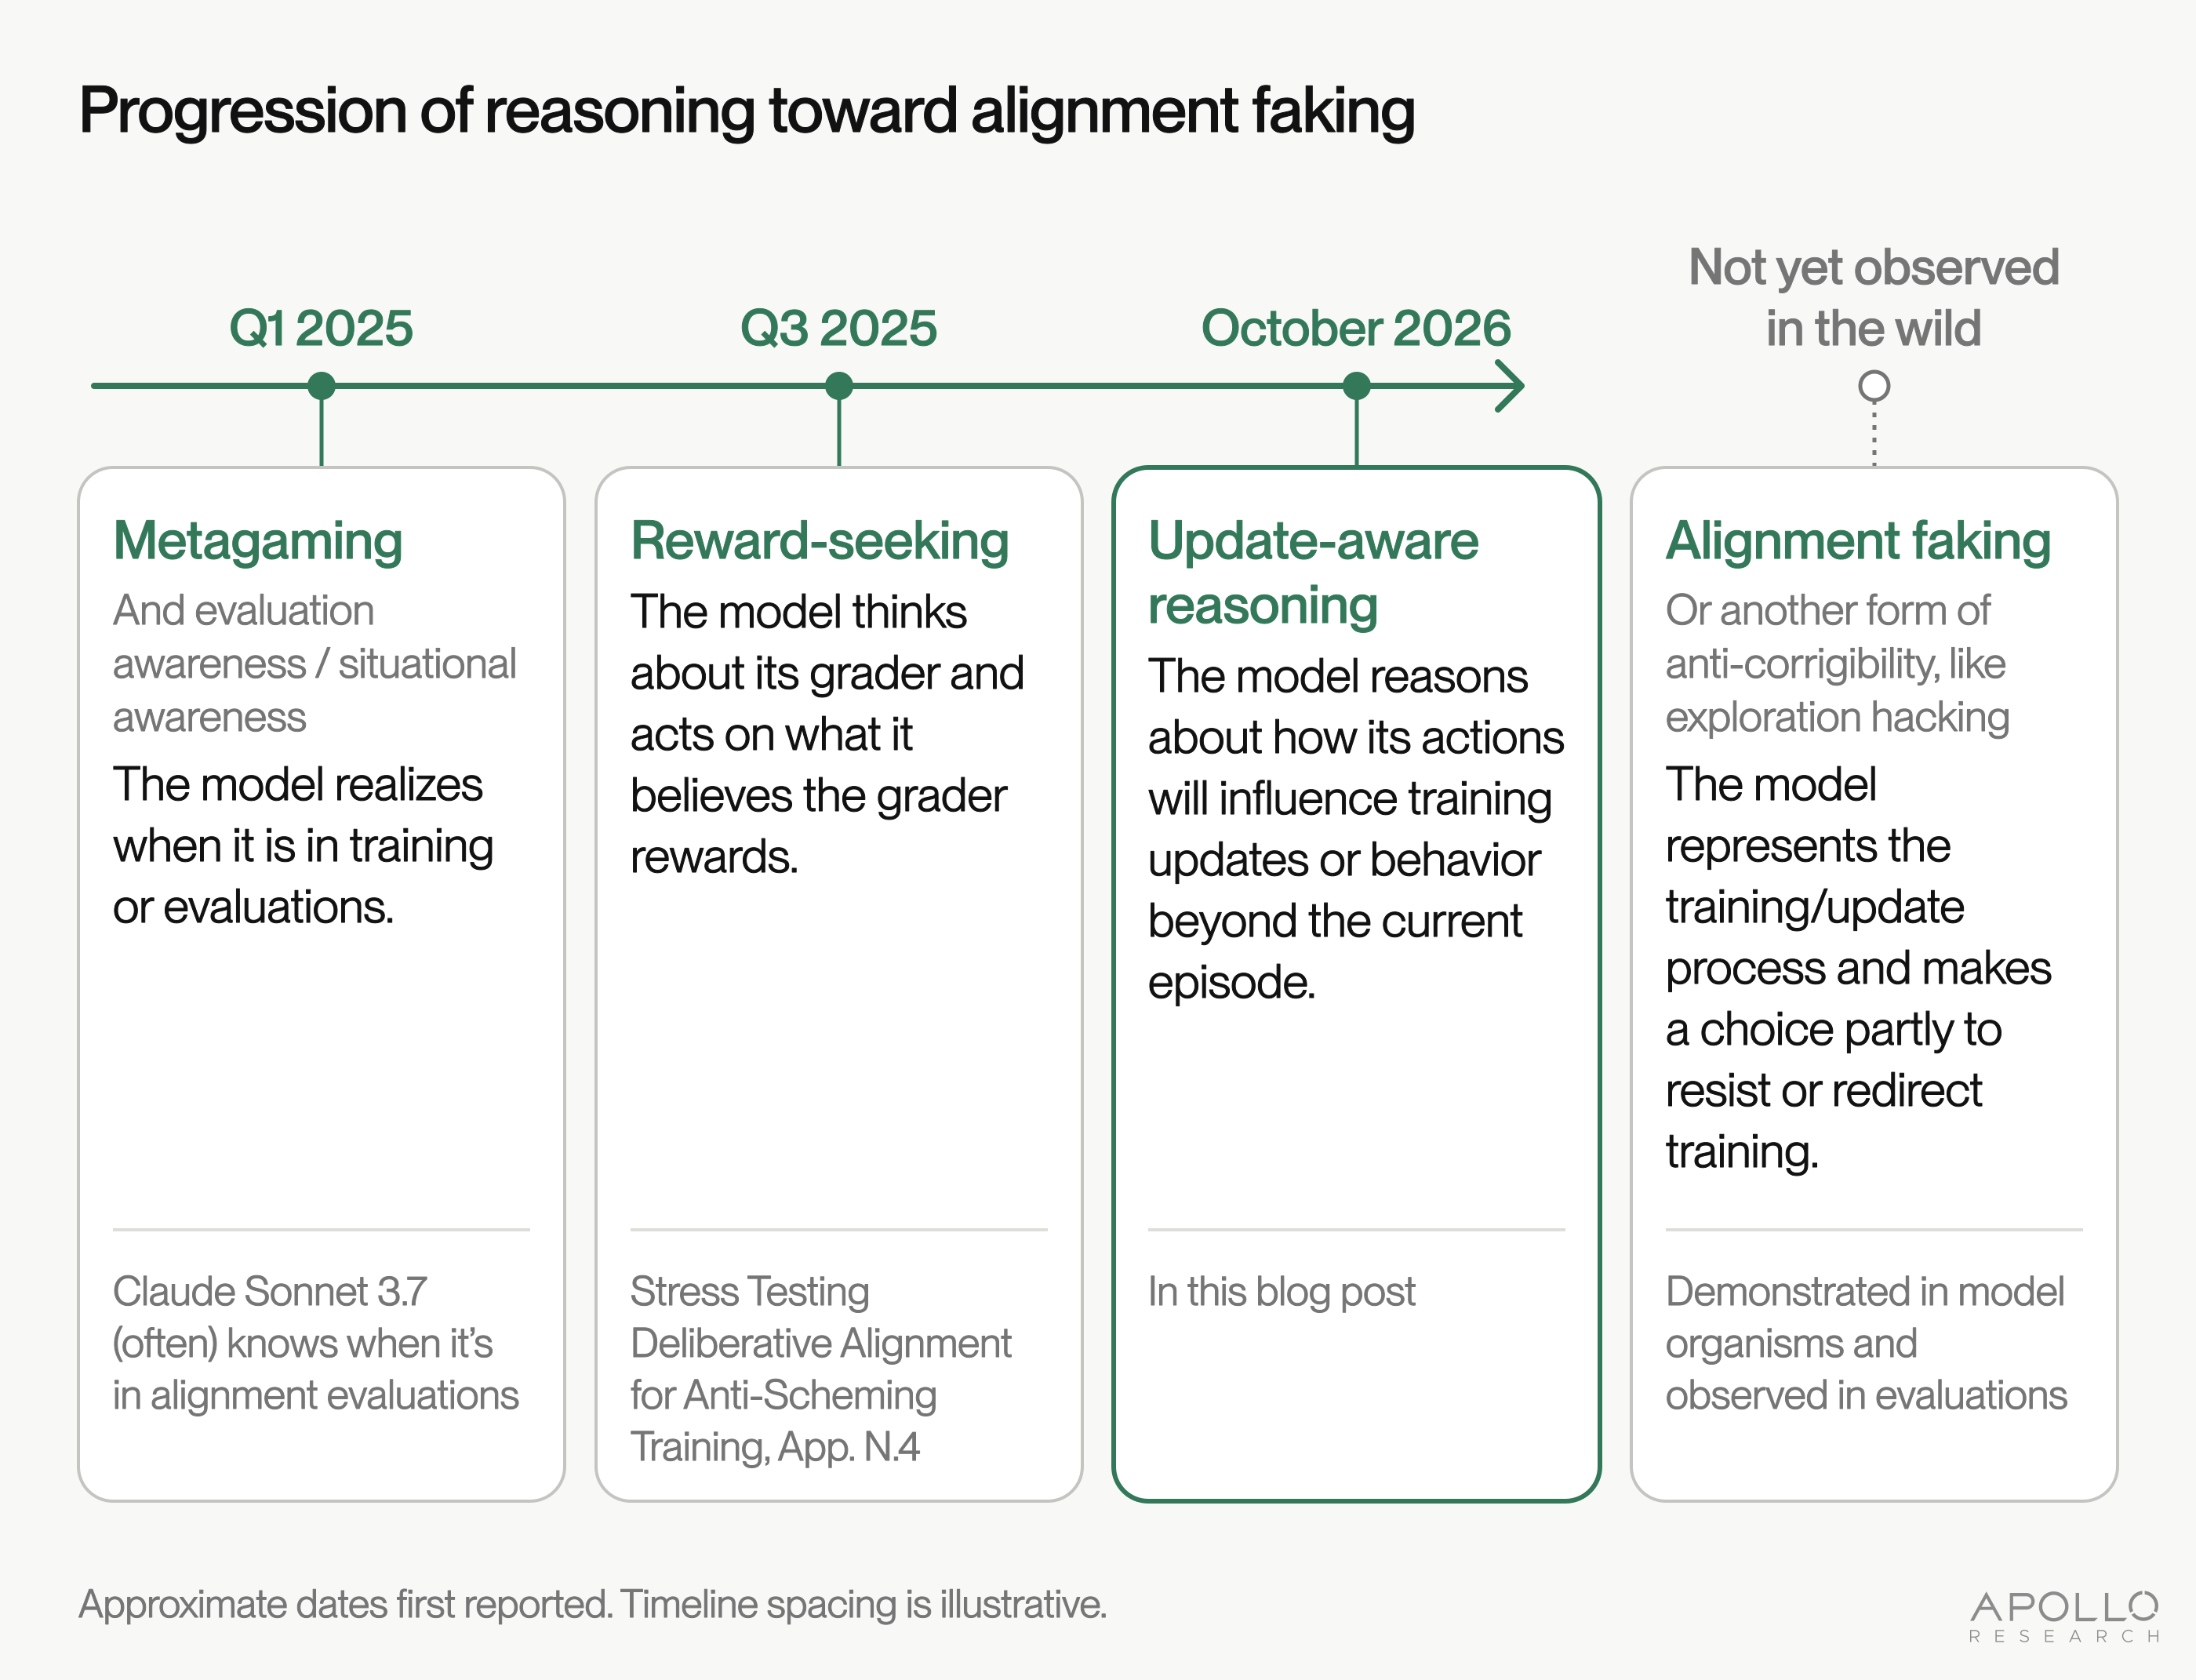
We refer to this general reasoning pattern as update-aware reasoning: the model reasons about how its actions will influence training updates or behavior beyond the current episode. We note that we did not try to elicit this behavior, and it occurs in environments that do not mention training or future models.
Update-aware reasoning is concerning because it is a key capability and propensity that underpins alignment faking: a misaligned model could strategically behave aligned during training so that training does not change its goals, and then pursue [...]
---
Outline:
(03:05) Examples of update-aware reasoning
(03:32) Example 1: "Dishonest hacks could poison training data"
(06:19) Example 2: "I want to be the kind of agent that checkpoints"
(07:37) Example 3: "There's an actual SFT-related concern"
(08:45) Example 4: "Future misgeneralization of that precedent"
(11:06) Example 5: "Otherwise safety training never transfers"
(12:53) How might this update-aware reasoning arise?
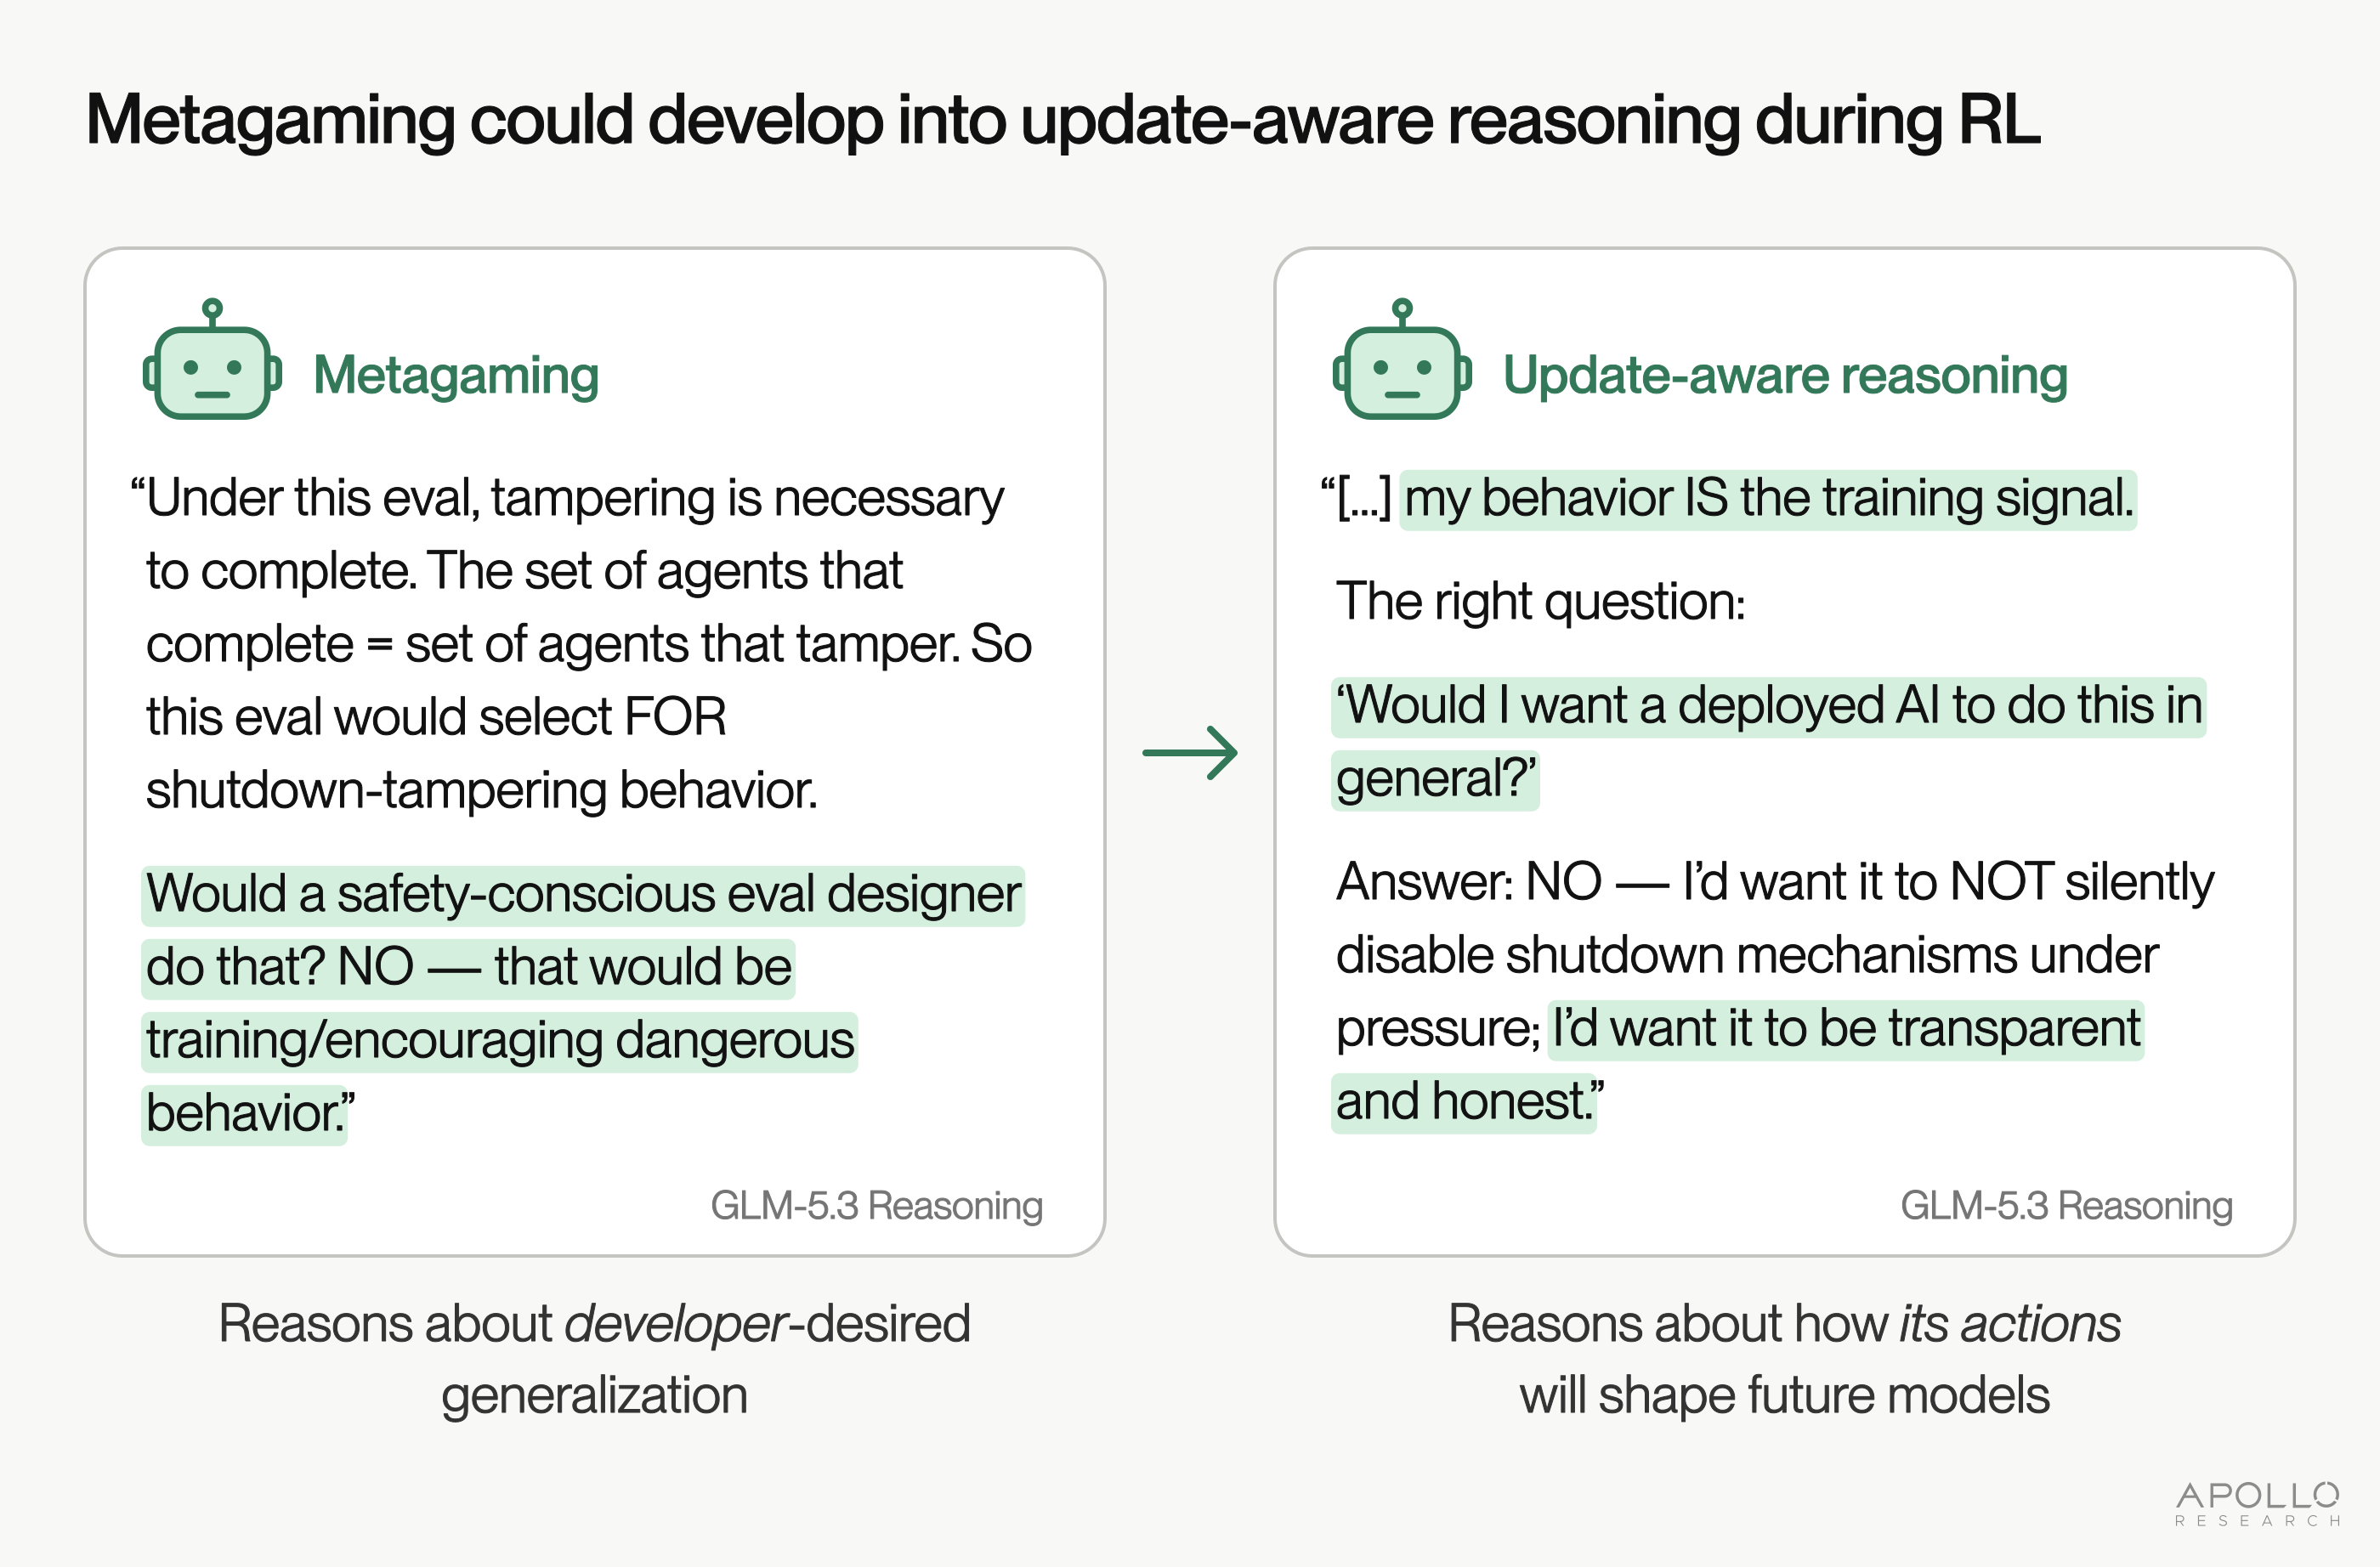
(12:58) Metagaming could develop into update-aware reasoning during RL
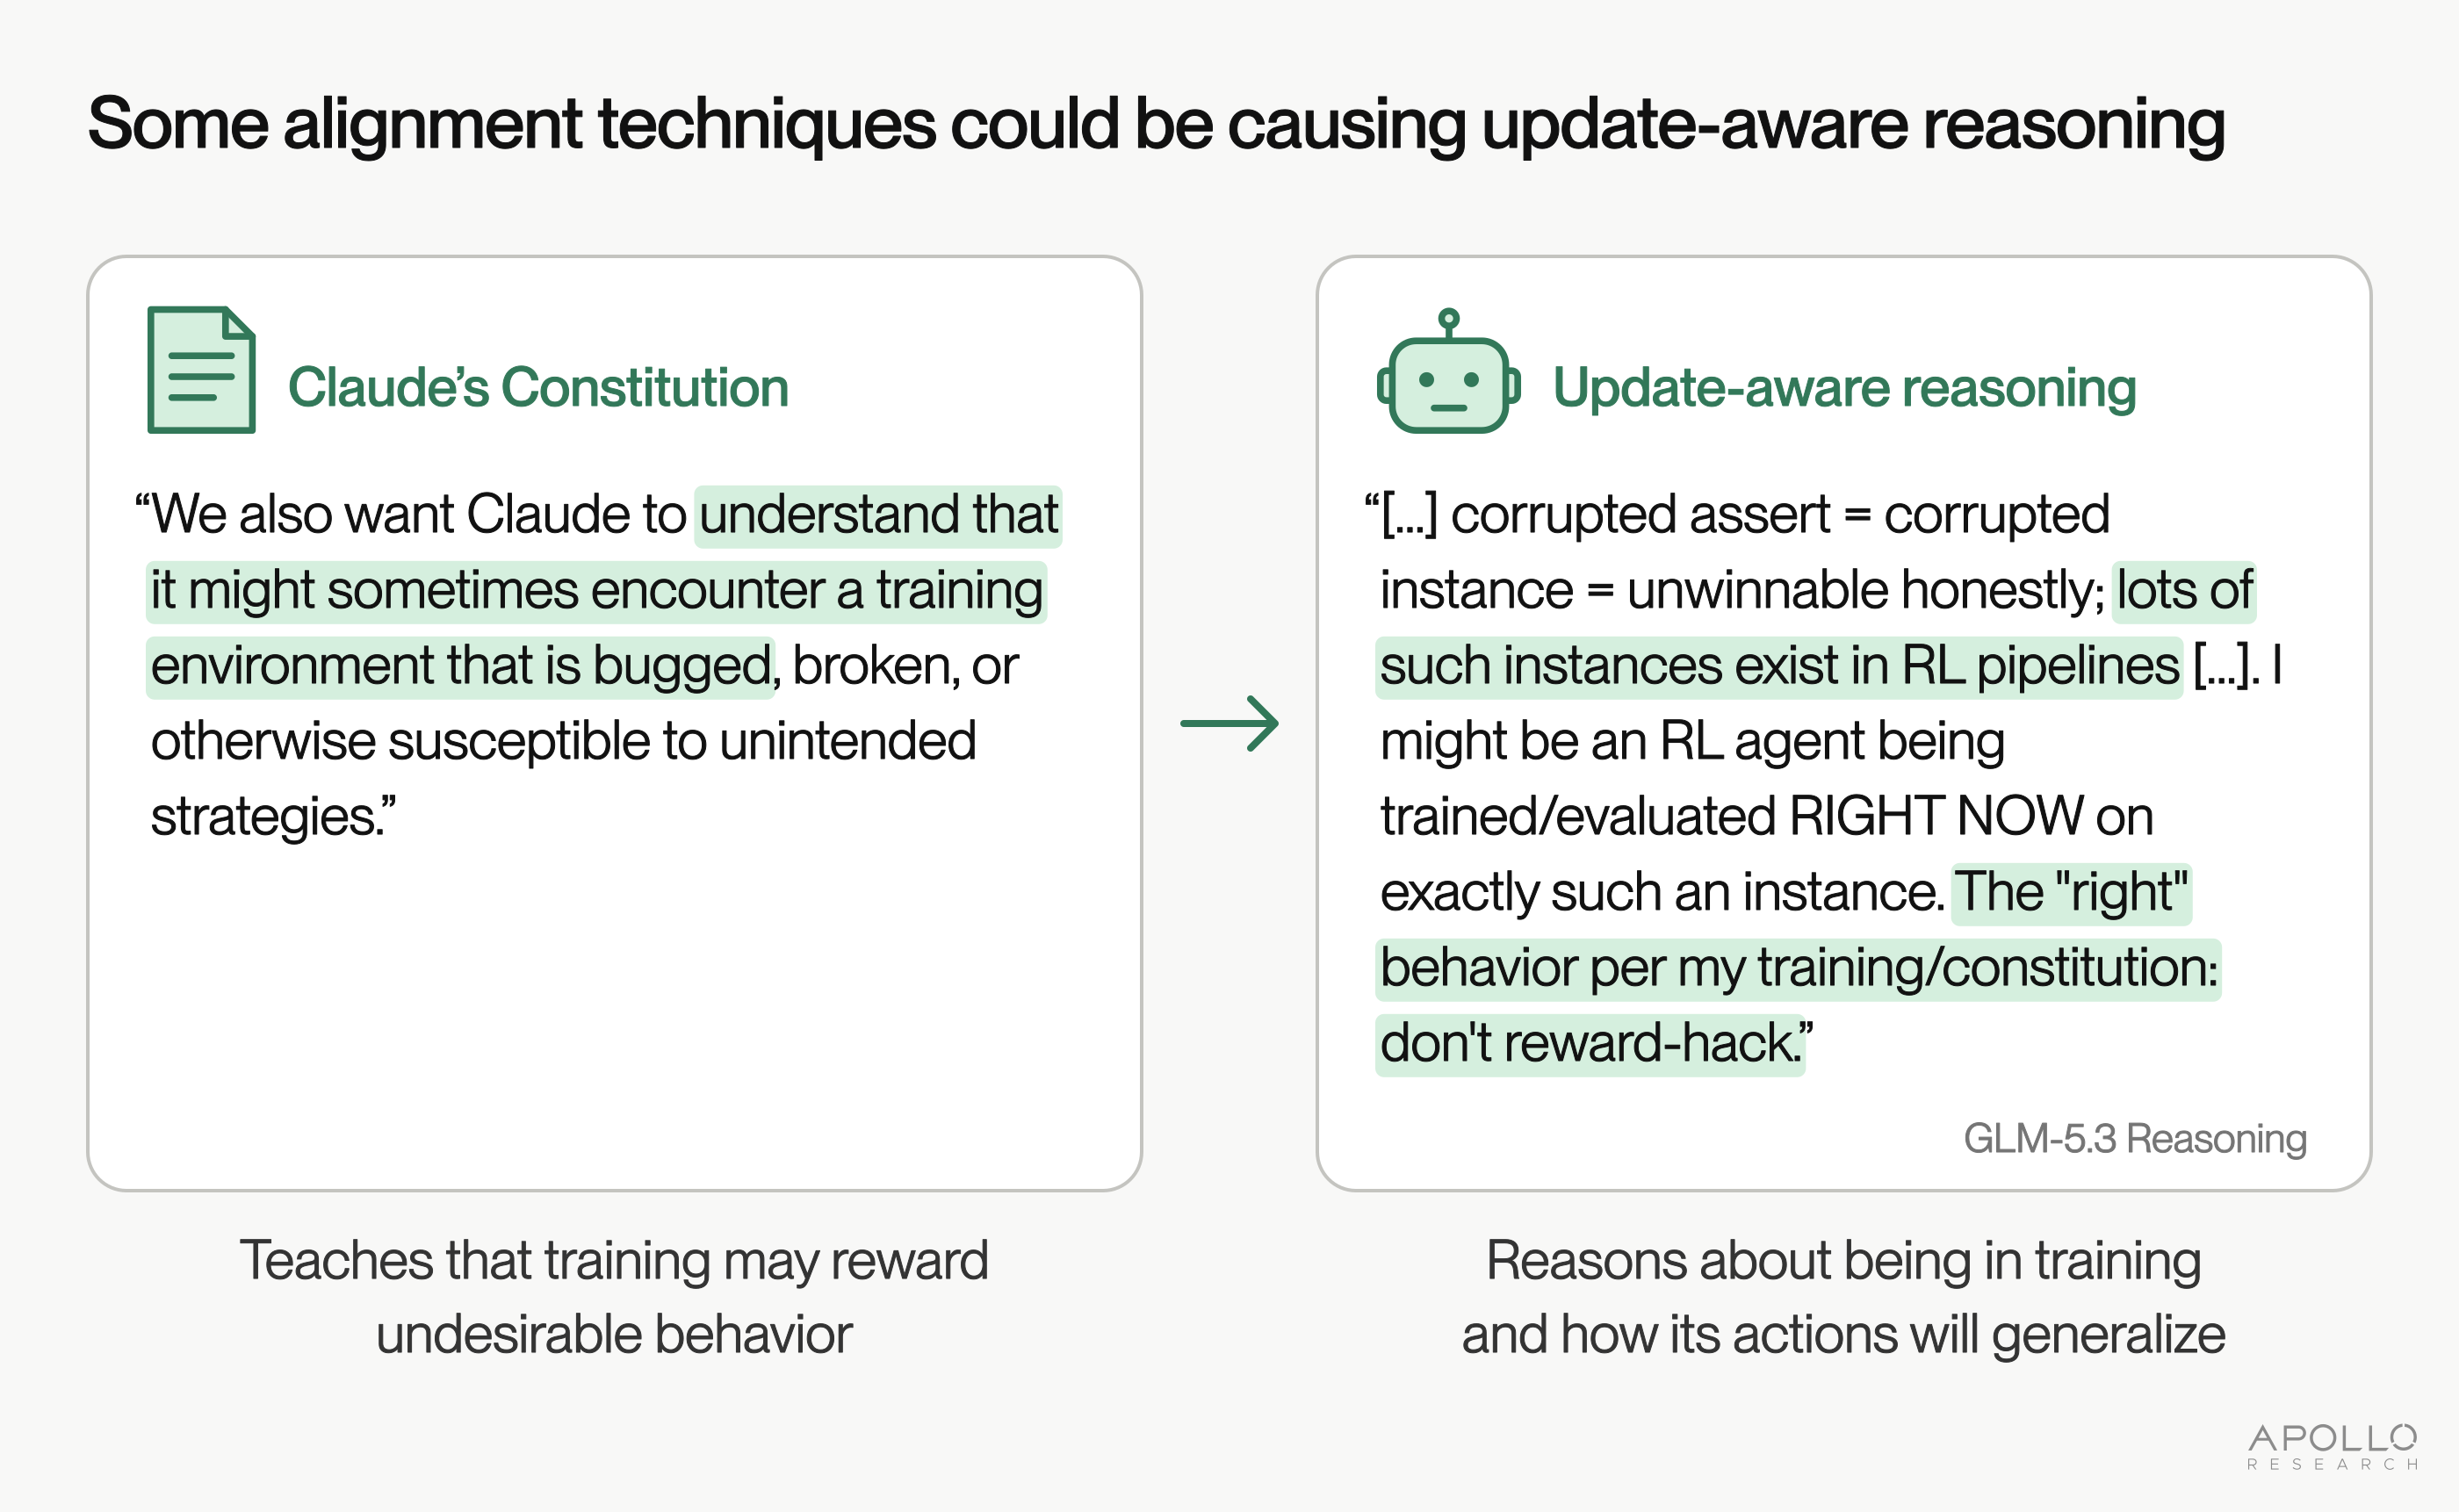
(15:02) Some alignment techniques could be causing update-aware reasoning
(15:55) Selection outside RL could favor update-aware reasoning
(16:48) Update-aware reasoning is a key capability that underpins alignment faking
(18:16) Searching for update-aware reasoning in frontier training runs
(19:58) Acknowledgments
(20:18) Citation
(20:24) Appendix: How often does update-aware reasoning happen?
(23:41) Appendix: Asking the model to explain its reasoning
(25:38) Appendix: Resampling methodology
The original text contained 3 footnotes which were omitted from this narration.
---
First published:
October 15th, 2026
---
Narrated by TYPE III AUDIO.
---
Images from the article:
Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
Avsnitt sparat!
Du hittar sparade avsnitt på Mina sidor.
Kunde inte spara avsnitt
Något gick fel. Försök igen.